Common Voice Scripted Speech v27 and Spontaneous Speech v5 are here
Scripted Speech v27 and Spontaneous Speech v5 are now live on the Mozilla Data Collective platform.
Scripted Speech v27 and Spontaneous Speech v5 are now live on the Mozilla Data Collective platform.

Lost In Transcription: Advancing Speech Recognition for Underserved Linguistic Contexts This competition evaluates performance on real-world bilingual dialogues in Indonesian-Javanese, Nahuatl-Spanish, and Spanish-English. For speech technologies to truly have an impact on the world, they must adapt to how people actually communicate in digitally-mediated settings.
Helping organisations participate more directly in the AI economy while making it easier for AI builders to discover responsibly sourced datasets. Earlier this month, we shared a preview of Compensated Datasets and our vision for creating more transparent ways for organisations to participate in the AI economy while retaining agency
Mozilla Common Voice is a massively multilingual platform for collecting speech data to train automatic speech recognition (ASR). Its mission is simple: to make language technology understand everyone’s mother tongue. But for datasets to be genuinely useful, they also need to be manageable. Many of the larger Common Voice
New collaboration expands visibility for community-governed language datasets and improves exploration of linguistic resources, services and tools. Mozilla Data Collective datasets are now discoverable through CLARIN’s Virtual Language Observatory, making it easier for researchers, developers and language technology practitioners in Europe to find multilingual and community-centered datasets
Mozilla Data Collective was built to redefine how AI data is created, shared, and governed. As part of our mission to be the data sharing platform for human agency and fair value exchange, we have long-teased what so many partners and community members have requested: a tangible way to
Why fine-tuning Whisper is a dataset problem OpenAI's Whisper changed what's possible in speech recognition: a single multilingual model with strong zero-shot performance across dozens of languages. But "dozens" is the catch. But for the long tail of the world's
For more than 75 years, Radio Free Europe/Radio Liberty (RFE/RL) has promoted democratic values by providing accurate, uncensored news and debate in countries where a free press is threatened. RFE/RL reaches more than 44 million people every week across 18 countries, in 24 languages, including Persian, Russian,
In this post, we walk you through how to create a useful dataset sample as a preview of your dataset, and guide you in uploading it to the MDC platform.
The problem with "low-resource" machine translation Most production machine-translation systems in 2026 are still trained on a fairly narrow set of language pairs: the 50 or so for which the open web supplies enough parallel text to push BLEU scores into useful territory. Below that line,
A curated list of 15 text-to-speech training datasets for teams shipping production voice models in 2026 covering emotional, multi-speaker, audiobook-derived, non-Latin script, indigenous-language datasets and more.
Most voice assistants listen and respond in a handful of languages. Try to build one for your home that speaks your language, though, and you quickly run into a wall: the training data does not exist, or it is locked behind licences that make it unusable for open source projects.
data contributors
Today, we're excited to share a new way for dataset providers to better understand how their datasets are being used on Mozilla Data Collective with a new data provider analytics portal.
News
When you ask a voice assistant a question in English, French, or Mandarin, the underlying models have been trained on billions of words and millions of hours of speech. Ask the same question in Bafia, Mada, or Suundi, and the technology simply doesn't know how to listen. The

News
Today, we're excited to share a new way to stay informed about the latest datasets on Mozilla Data Collective - the ability to subscribe to get updated about similar datasets to your previous downloads.
News
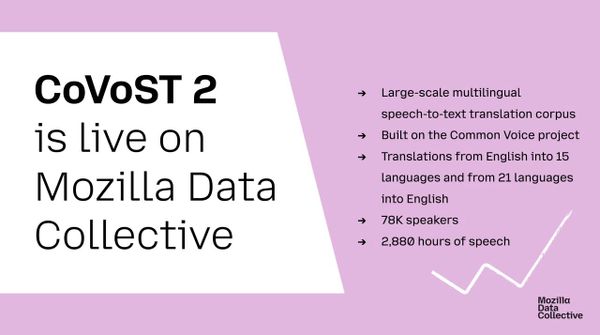
In 2020, Meta introduced a new benchmark dataset based on Mozilla Common Voice. CoVoST 2 has 34 translation directions for audio to text machine translation. This is one of the most widely-used benchmark datasets for speech translation, with nearly 400 citations on Google Scholar. The dataset is based on
News
New capabilities expand uploader control over access and compensation, while helping developers discover more representative datasets
data
Learn how we automatically generate Croissant metadata to describe datasets on the Mozilla Data Collective platform, making them more discoverable.
Guides
In this guide, we'll walk through the different options available on the platform for sharing your contact information with downloaders and setting expectations about how downloaders or other community members can reach out to you.
FAQ
Fields that make up the terms of use of your dataset cannot be edited after publishing.
Community Authors
The origin of Swahili language Swahili originated from the Indian ocean and has its route from the contacts of Arabian traders with the inhabitants of the east coast of Africa over many centuries. Swahili is the lingua franca of most east african countries spoken largely in countries such as Tanzania,
News
We're excited to share that the Mozilla Data Collective Data Assistant is now available in Alpha. Visit https://mozilladatacollective.com/chat to get started.
Author: Alek Tarkowski For the last twenty five years, standardized open licenses were increasingly seen as a main tool for democratizing access to knowledge. Over less then a decade, a relatively narrow set of canonical choices emerged: the Creative Commons licensing stack https://creativecommons.org/licenses/list.en, coupled with
News
Today we’re so excited to announce exciting platform changes to Mozilla Data Collective that bring us closer to fulfilling our promise to give everyone the Data Platform for Human Agency and Fair Value Exchange.